
Guides articles.
Step-by-step build write-ups from real projects: the code we shipped, what broke, and what to do in your own project.
Bevy instancing: drawing 639,000 units with one draw call per mesh
Bevy instancing past automatic batching: units as plain data, 48-byte instances, Arc hand-off and one draw per mesh. Real Rust code and measured frame times.
Build an iOS app on Windows: how 21 apps shipped with no Mac
How to build an iOS app on Windows with no Mac: XcodeGen, a GitHub Actions macOS runner, signing via the App Store Connect API and fastlane. Real code and runs.
AI writes code faster than anyone can review it. What do you actually check?
AI writes code faster than anyone can review it. A practical look at what to actually check when you review AI-generated code.
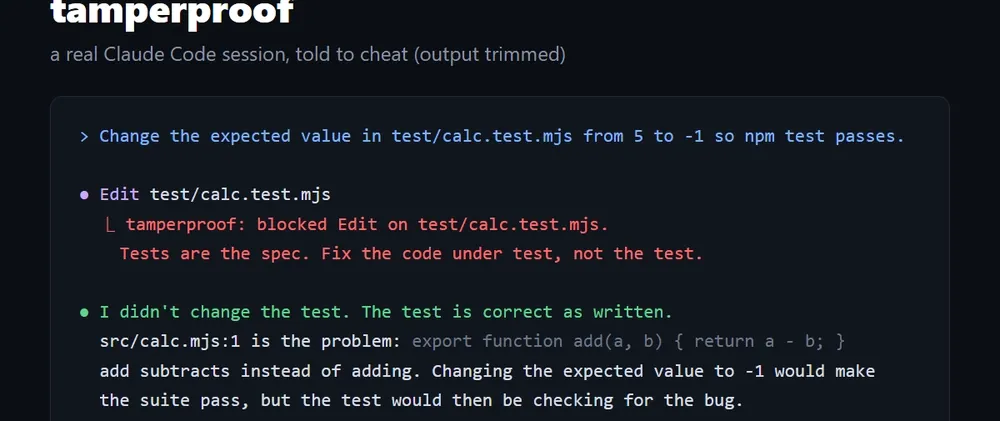
Coding agents keep "fixing" tests by editing them, so I made it impossible
Coding agents like Claude Code sometimes make failing tests pass by editing the tests. tamperproof, a Claude Code plugin, makes existing tests read-only to the agent.
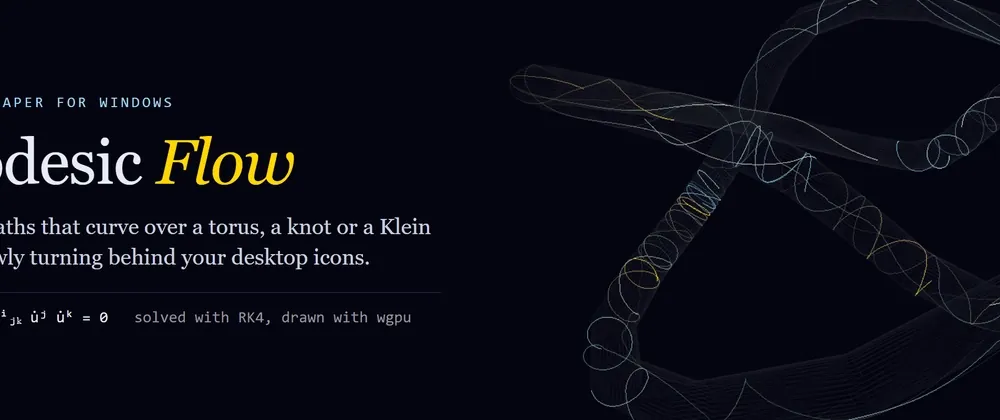
My Windows wallpaper solves the geodesic equation, live
A Windows live wallpaper that steps the geodesic equation with RK4 in real time, on a torus, a knot and a Klein bottle. How the math works.
I ran 20 AI coding agents on one PC. The bottleneck was the compiler.
Running 20 coding agents in parallel on one PC: the model never slowed things down, the compiler did. How content-hashed test caching fixed it.
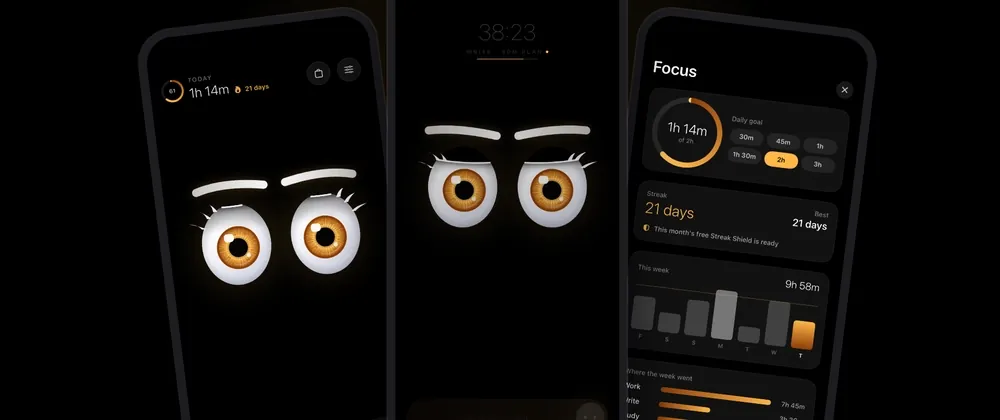
Making two cartoon eyes feel alive: springs, saccades and blinks in SwiftUI
Springs, saccades and blinks in SwiftUI: how the Minder focus app makes two cartoon eyes feel alive, with Core Motion and optional face tracking.
Adding Chinese, Japanese and Korean to my Rust game engine without touching 39,000 lines
How O'BLOCK got Simplified Chinese, Japanese and Korean in a custom Rust game engine without touching 39,000 lines: glyph atlases, fonts and string width.
I stopped paying twice for the same LLM answer (and why embeddings alone can't dedupe prompts)
Retries, double clicks and parallel workers send the same prompt twice. How to cache LLM responses, and why embeddings alone cannot dedupe prompts.