
By Matt Busel, who built the apps, crates and game he writes about · every number links to its source and every dataset is downloadable (methods) · corrections · featured in Kirino, gamebiz, This Week in Rust, New Mobile Life, By-Press
Context engineering: pgvector up 74%, Pinecone down 36% on PyPI
On this page · 8 sections
Short answer: Context engineering is the job of choosing what goes into a model's context window, and the download data says builders now do it with boring tools. Across 17 Python packages we pulled from PyPI, pgvector (vector search inside plain Postgres) grew its share of downloads 74% since May, a 2009-era keyword ranker grew 55%, and the dedicated vector databases and RAG frameworks lost 35% to 76%.
TL;DR: In October so far, pgvector was downloaded 30.9 million times, more than Qdrant, Chroma and Pinecone combined (21.4 million); in May it was about half their total. rank-bm25, a keyword search library, pulled 7.2 million downloads this month, more than Pinecone (3.3 million) and Chroma (6.6 million). LlamaIndex, the framework built around "chat with your documents", lost 76% of its share. The million-token context window did not kill retrieval; it killed the startups that sold retrieval as a separate product.
Key numbers
| What | Number | Source, checked Oct 26 2026 |
|---|---|---|
| pgvector downloads, Oct 1-25 2026 | 30.9M (share +74% vs May) | pypistats.org |
| Qdrant + Chroma + Pinecone clients, Oct 1-25 | 21.4M combined | pypistats.org |
| Pinecone client share change, May to Oct | -36% | pypistats.org |
| rank-bm25 (keyword search) share change | +55% (7.2M downloads in Oct) | pypistats.org |
| llama-index share change | -76% | pypistats.org |
| langchain share change (langgraph) | -34% (+14%) | pypistats.org |
| Point where Gemini 2.5's Pokemon agent started looping | "significantly beyond 100,000 tokens" | Drew Breunig, AGNTCon talk |
The million-token pitch broke in the appendix
Drew Breunig, who is writing O'Reilly's Context Engineering Handbook, gave a talk at AGNTCon this week that hit the Hacker News front page. His recap of late 2024: "RAG is dead", just make the window huge and "put the entire internet in it."
Then the receipts. Breunig points to the Gemini 2.5 technical report, where Google's own Pokemon-playing agent "began repeating actions from its history instead of synthesizing new plans" once its context grew well past 100,000 tokens. That is one tenth of the window Google was marketing. In his words: "I'm convinced the marketing people never read the appendix."
He names four ways long context fails: poisoning (a bad fact gets in and sticks), distraction (the model copies its own history), confusion (irrelevant facts steer the answer) and clash (tools and instructions fight each other). Every one of them gets worse the more you stuff in. So the real skill is leaving things out.
Builders voted with pip install: retrieval moved into Postgres
We pulled monthly PyPI downloads for 17 packages that make up the context stack: vector stores, keyword search, RAG frameworks, memory layers and the two big model SDKs. Then we divided each by downloads of requests, the most boring package in Python, so a site-wide swing does not look like a trend.
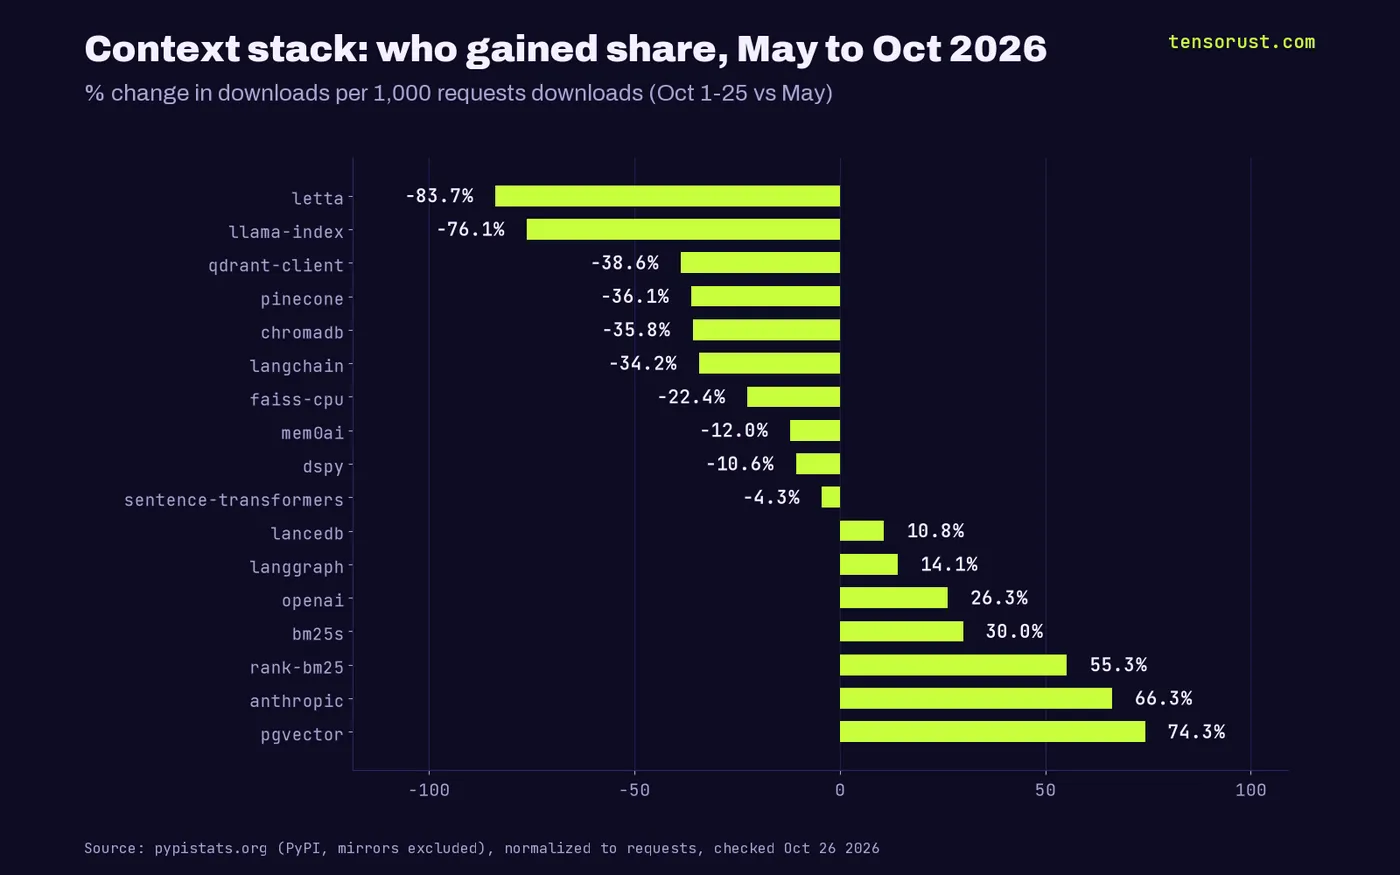
The winners are the dull ones. pgvector, an extension that adds vector search to the Postgres database you already run, gained 74% share. rank-bm25, an implementation of BM25 (a keyword relevance formula from the 1990s, plain word matching with smart weighting), gained 55%. Its faster cousin bm25s gained 30%.
The losers are the products that asked you to run something new. Qdrant's client fell 39%, Pinecone 36%, Chroma 36%, FAISS 22%.
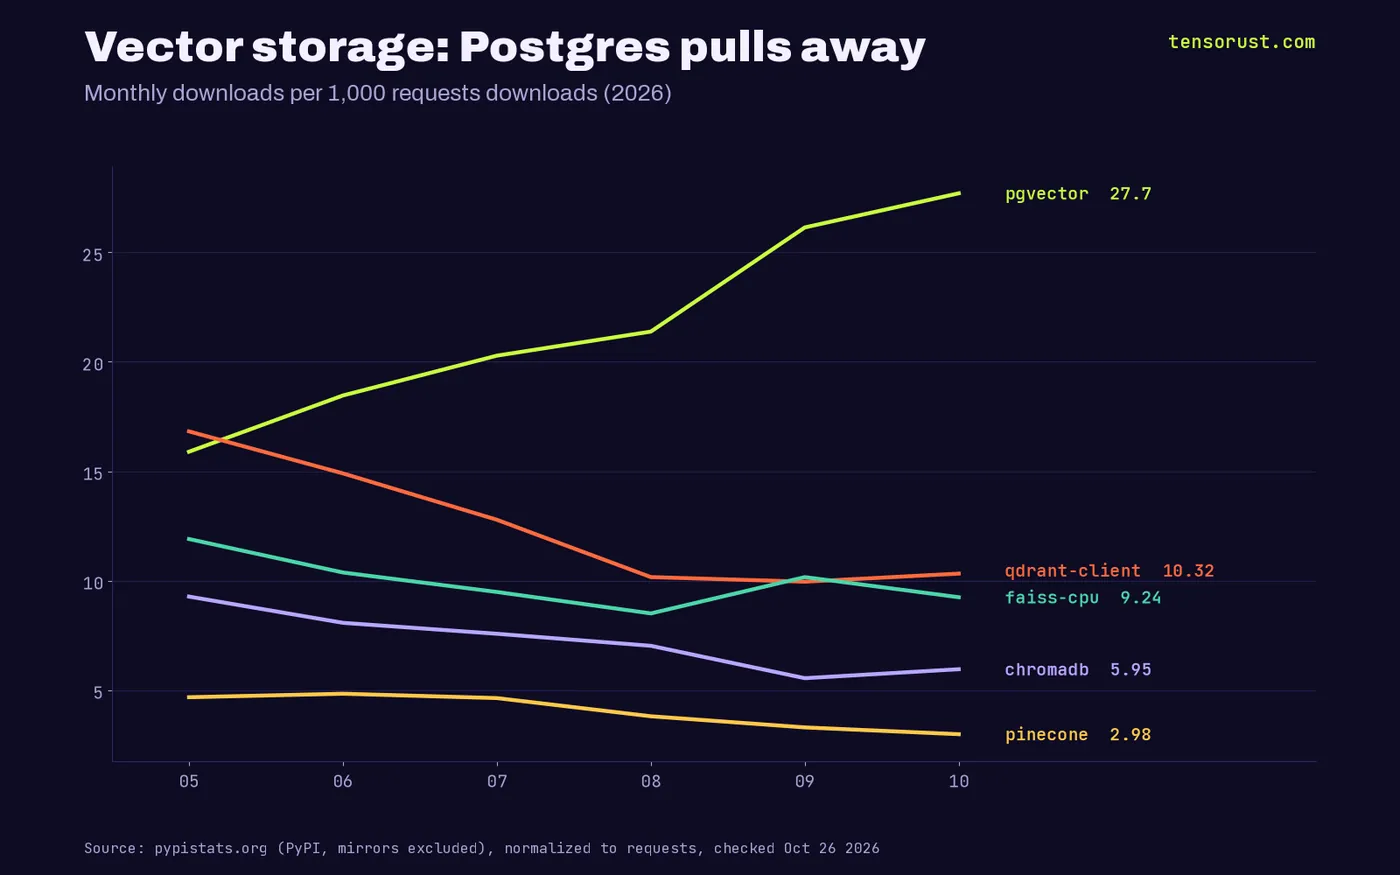
In May, Qdrant, Chroma and Pinecone together out-downloaded pgvector almost two to one (49.2 million vs 25.4 million). In the first 25 days of October, pgvector beat all three combined, 30.9 million to 21.4 million. That flip took five months.
Follow the money: who wins, who loses
The dedicated vector database was the hottest pitch of the RAG era: a new database, a new bill, a new vendor in your stack. The data says the market decided a vector is just another column.
The winners do not send invoices. Postgres is free, pgvector is free, BM25 is free. The money that used to go to a separate retrieval vendor now stays with the team, or flows to whoever hosts their Postgres.
The model labs win too. The anthropic SDK grew its share 66% and openai 26% over the same window. Breunig's point lands here: as the labs ship features like built-in memory and skills, they absorb jobs that used to need a framework in the middle.
Frameworks: LangChain shrinks, LangGraph holds
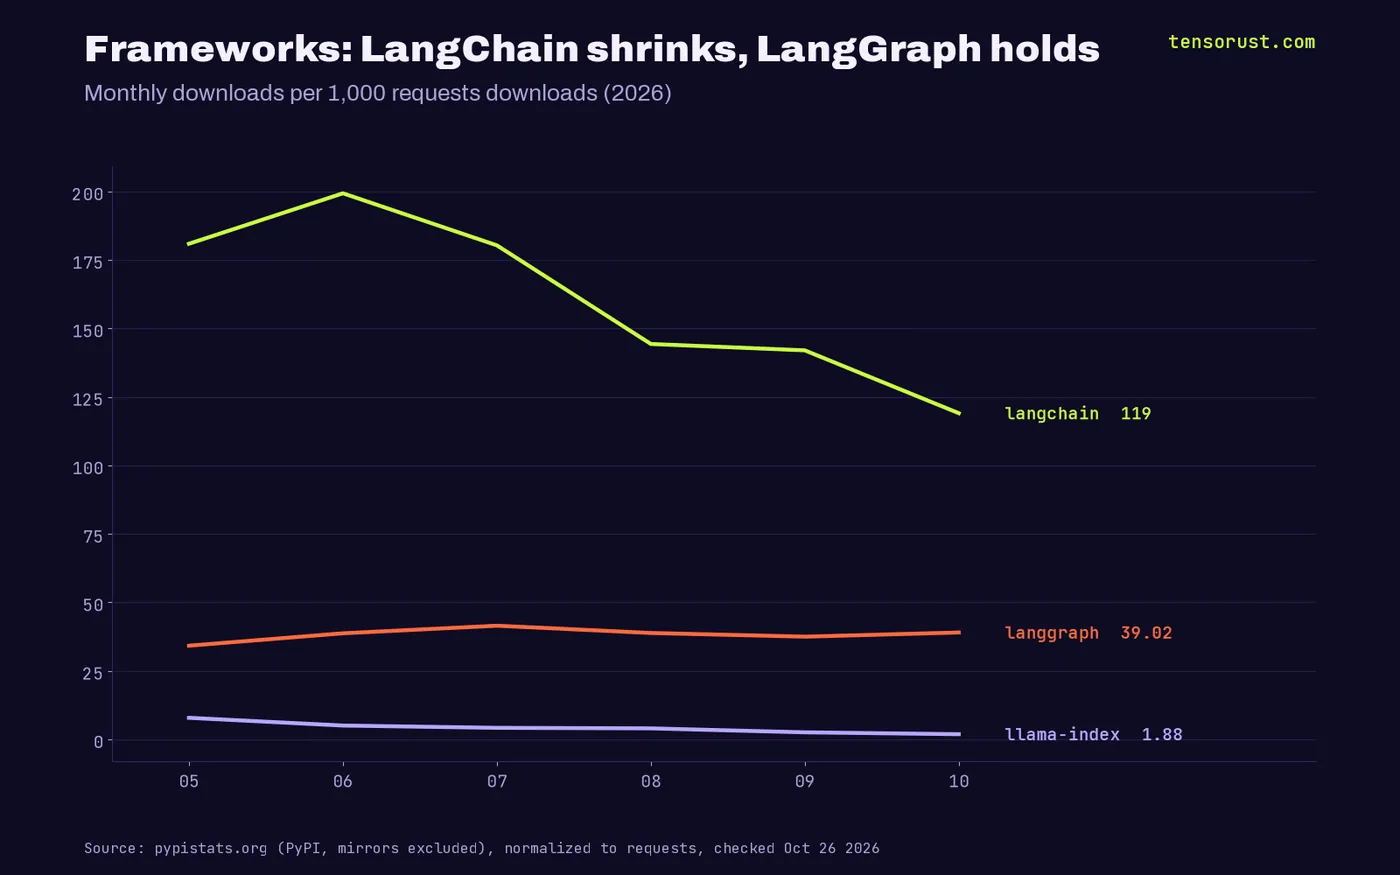
LangChain lost 34% of its share since May, and LlamaIndex lost 76%. Those were the "chat with your PDFs" frameworks of 2023, built when retrieval was the whole trick.
LangGraph, the same company's agent-orchestration library, gained 14%. DSPy (fell 11%) and the memory layer mem0 (fell 12%) mostly held. Our read: people still want structure for agents, but they stopped paying a framework tax just to fetch documents. Letta fell 84%, but from a base of about 108,000 downloads a month, so treat that one as noise.
The September crash that was not
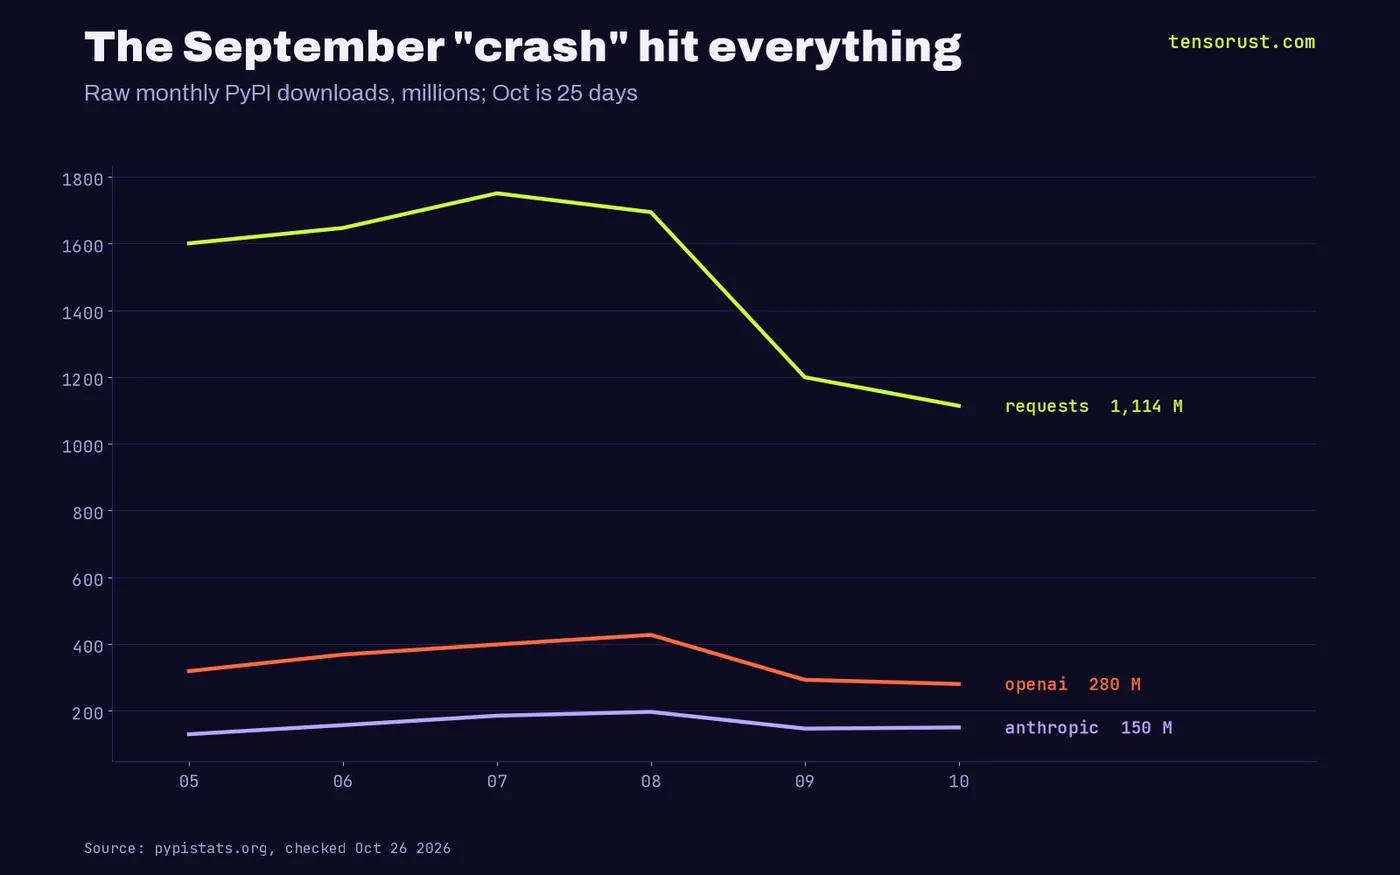
A warning if you pull this data yourself. Raw downloads for nearly everything on PyPI fell about 30% from August to September: requests dropped 29%, openai 32%, anthropic 25%. Nobody stopped using requests. That is a counting shift across the whole index, and anyone charting raw numbers this month will "discover" an AI collapse that is not there.
That is why every share number in this piece is per 1,000 requests downloads. Download counts also include CI machines and bots, so they measure installs, not people. They are still the cleanest public signal of what builders actually ship. The full table is in the data download below.
What this means for you
If you are building an AI feature, do the boring thing first. Put your embeddings in the Postgres you already have with pgvector, add BM25 keyword search next to it, and keep the context you send small and clean. Breunig says he starts checking around 200,000 to 300,000 tokens and resets before a big job rather than fill the window.
- Step 1: store embeddings in a pgvector column next to the rows they describe, so one query filters by user, date and meaning together.
- Step 2: run BM25 keyword search alongside it, because exact names, error codes and part numbers are where pure vector search misses.
- Step 3: send the model the top few results, not the top hundred, and start a fresh session before the history starts steering the answers.
Before you add a new database or framework, ask what it does that a table and a WHERE clause cannot. Then read our LLM hub, the LLM articles and our breakdown of the LLM price war, because cheaper tokens make it tempting to stuff more in, and the appendix says that is exactly where agents break. More in AI agents.
If your coding AI keeps drifting from what you asked, that is context distraction in your own editor. Our $29 AI Builder Kit is five offline apps that keep your AI building what you meant, on any model including a local one. If it does not, we keep working with you at no extra cost until it does.
Sources
- Drew Breunig, The State of Context Engineering (AGNTCon talk transcript), Oct 24 2026
- Hacker News front page discussion, Oct 26 2026
- pypistats.org: pgvector, qdrant-client, pinecone, chromadb, faiss-cpu, lancedb, checked Oct 26 2026
- pypistats.org: rank-bm25, bm25s, sentence-transformers, checked Oct 26 2026
- pypistats.org: langchain, langgraph, llama-index, dspy, mem0ai, letta, checked Oct 26 2026
- pypistats.org: openai, anthropic, requests, checked Oct 26 2026
First published here on tensorust.com on Oct 26, 2026. Related: .
Up next
More on LLMsOpenAI and Anthropic jobs: 1,472 openings, 702 for engineersOpenAI and Anthropic list 1,472 open jobs today: 702 engineers, 305 in sales, median pay $307K to $347K. The labs sell AI. They are not replacing staff.Read it next →Cite this
Free to cite and reuse under CC BY 4.0 with a link back. How it was collected: methods. Spotted an error? Corrections.
Did this answer your question?
Get the next one by email.
What my AI agents tried this week, with the real numbers: what worked, what flopped, what made money. One email when there is something worth reading.
No spam, never sold. Every email has a one-click unsubscribe.
What are people saying about this? Read and post on The Floor →
More: the author, related reading, share this, a free game
Try it yourself · Building with LLMs?
Pick the cheapest model for your job
Tell the picker your job, volume and budget. It prices all 71 models and gives 3 picks with the reasons.
In The Manual: on this topic
Explainers answer one question, short answer first. Guides walk you through it step by step.
- Explainer · AI, LLMs and agentsClaude Code vs Cursor: what each costs now that SpaceX owns Cursor
- Explainer · Shipping and selling429 Too Many Requests: what it means and how long to wait
- Explainer · AI, LLMs and agentsWhat is prompt caching?
- Explainer · Money and the economyWhat is circular financing in AI?
Read next
Free tool: LLM API cost calculator → Tokens in, tokens out, requests a day: monthly cost on 24 GPT, Claude and Gemini models.
- AI · Oct 26, 2026 · 6 min readOpenAI and Anthropic jobs: 1,472 openings, 702 for engineers
- AI · Oct 26, 2026 · 6 min readMicrosoft Decision-1 is Qwen: Microsoft ships 21 Qwen models, 13 Phi
- AI · Oct 26, 2026 · 7 min readIBM says open AI is 90% as good. The top 10 are all Chinese