
By Matt Busel, who built the apps, crates and game he writes about · every number links to its source and every dataset is downloadable (methods) · corrections · featured in Kirino, gamebiz, This Week in Rust, New Mobile Life, By-Press
Qwen ate open source: 58% of new fine-tunes run on Chinese AI
On this page · 11 sections
- Key numbers
- Korea's study just confirmed what the whole internet already did
- How we counted 277,029 models
- Chinese bases have held the majority for ten straight months
- Llama is the real loser, and Meta did it to itself
- Follow the downloads: half of all LLM pulls are Qwen
- Korea paid 200 billion won and lost its own language
- The sovereign AI scorecard is brutal
- What they won't say about "AI safety from China"
- What this means for you
- Sources
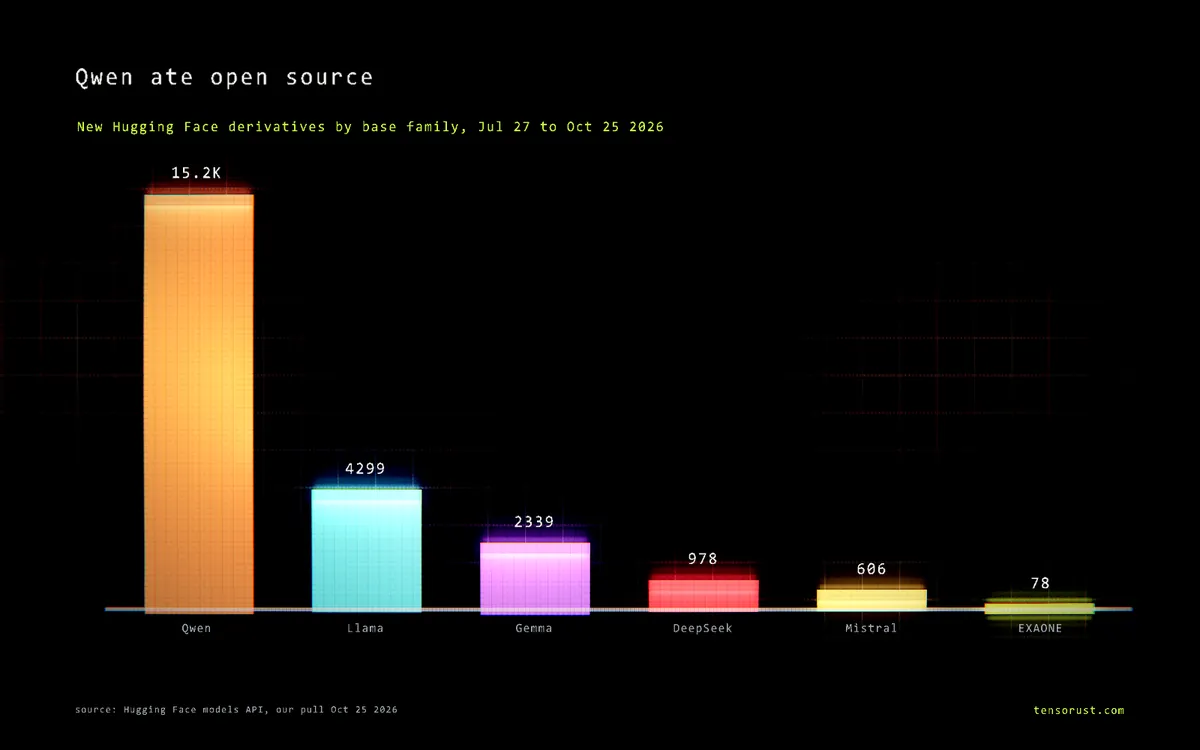
Short answer: Yes, Chinese base models now run most of open-source AI. We pulled every text-generation model uploaded to Hugging Face since January 2025 (277,029 of them) and traced what each one was built on: in October 2026, 57.8% of new derivatives sit on a Chinese base, and Alibaba's Qwen alone is 51.0%. Meta's Llama, the model that started the open-weights boom, fell from 31.7% to 11.2%.
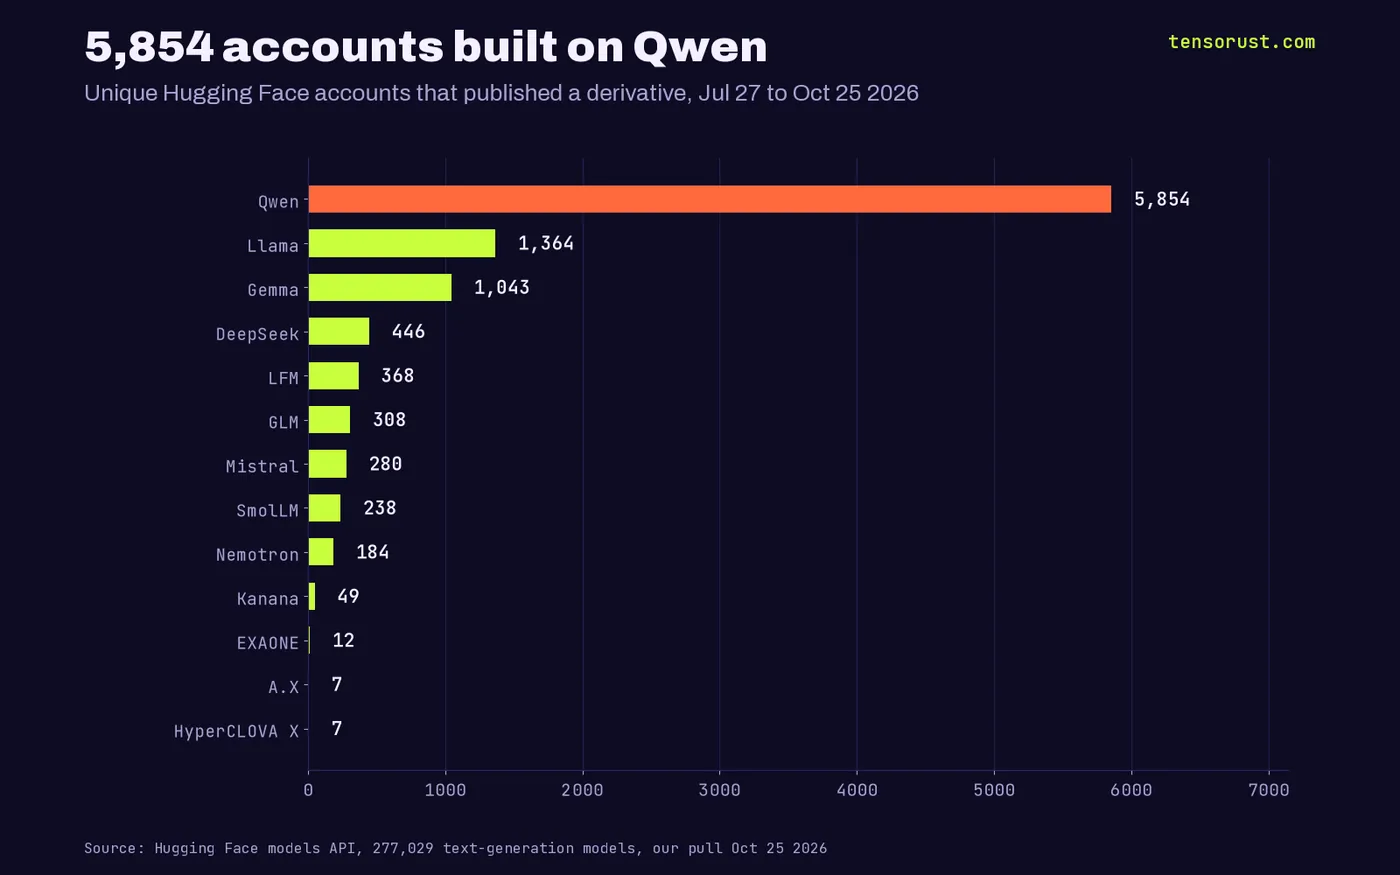
TL;DR: In the last 90 days, 5,854 different Hugging Face accounts published a model built on Qwen, against 1,364 for Llama and 1,043 for Gemma. Qwen also takes 50.0% of the last-30-day downloads among the 1,000 most downloaded text-generation models (413.3M downloads in total). Korea spent about 200 billion won on "sovereign AI" and kicked Naver out of the program for using Qwen parts, yet Chinese bases went from 13.9% to 45.1% of new Korean-language models in a single year, and LG's EXAONE got 78 new derivatives worldwide while Qwen got 15,193.
Key numbers
| What | Number | Source, checked Oct 25 2026 |
|---|---|---|
| New Hugging Face text-generation derivatives on a Chinese base, Oct 1 to 25 2026 | 57.8% (32.3% in Jan 2025) | Hugging Face models API, our pull |
| Qwen share of new derivatives, Oct 2026 | 51.0% (peak 71.0% in Feb 2026) | Hugging Face models API, our pull |
| Llama share of new derivatives | 31.7% (Jan 2025) to 11.2% (Oct 2026) | Hugging Face models API, our pull |
| Accounts that published a derivative, last 90 days | Qwen 5,854 / Llama 1,364 / Gemma 1,043 / EXAONE 12 | Hugging Face models API, our pull |
| Qwen share of 30-day downloads, top 1,000 text-generation models | 50.0% of 413.3M | Hugging Face models API, our pull |
| New Korean-language models on a Chinese base | 8.3% (2024), 13.9% (2025), 45.1% (2026) | Hugging Face models API, our pull |
| Korea-linked derivatives on Chinese bases, Jan to Aug 2026 | 49.3% (Qwen 864 of 1,845, 46.8%) | Korea Herald on the Rockbridge Network Korea study |
| Korea's sovereign AI support | about 200 billion won (about $151M) | Korea Herald |
Korea's study just confirmed what the whole internet already did
On October 21, Hanyang University professor Choi Seong-jin published a Rockbridge Network Korea report that hit Seoul like a slap: 49.3% of 1,845 AI model derivatives from Korea-linked Hugging Face accounts (January to August 2026) were built on Chinese foundation models. Qwen alone was 864 of them, 46.8%. LG's EXAONE, Korea's flagship, was fourth at 9.3%.
The local framing is "Korea has a China problem." Our read: Korea has the same problem as everyone else, it just measured it first. So we ran the count for the whole world.
A derivative here means a model that names another model as its parent on Hugging Face: a fine-tune, a quantized copy, a merge or an adapter. It is the cleanest public signal of what developers actually build on, because nobody uploads a fine-tune of a model they did not download and train.
How we counted 277,029 models
We pulled every model tagged text-generation on Hugging Face created from January 1 2025 to October 25 2026, newest first, through the public API. 164,194 of them name a parent model.
For each one we read the parent's name, then the parent's organisation, then the architecture tag, and mapped it to a family (Qwen, Llama, Gemma, DeepSeek, EXAONE and 40-odd more) and that family's home country. 8.7% of the last 90 days stayed unknown and we left them out of the shares rather than guess.
Spam is real on Hugging Face (one account can push 100 checkpoints in an hour), so we also counted unique uploading accounts. Every chart below is reproducible from the CSVs on this page.
Chinese bases have held the majority for ten straight months
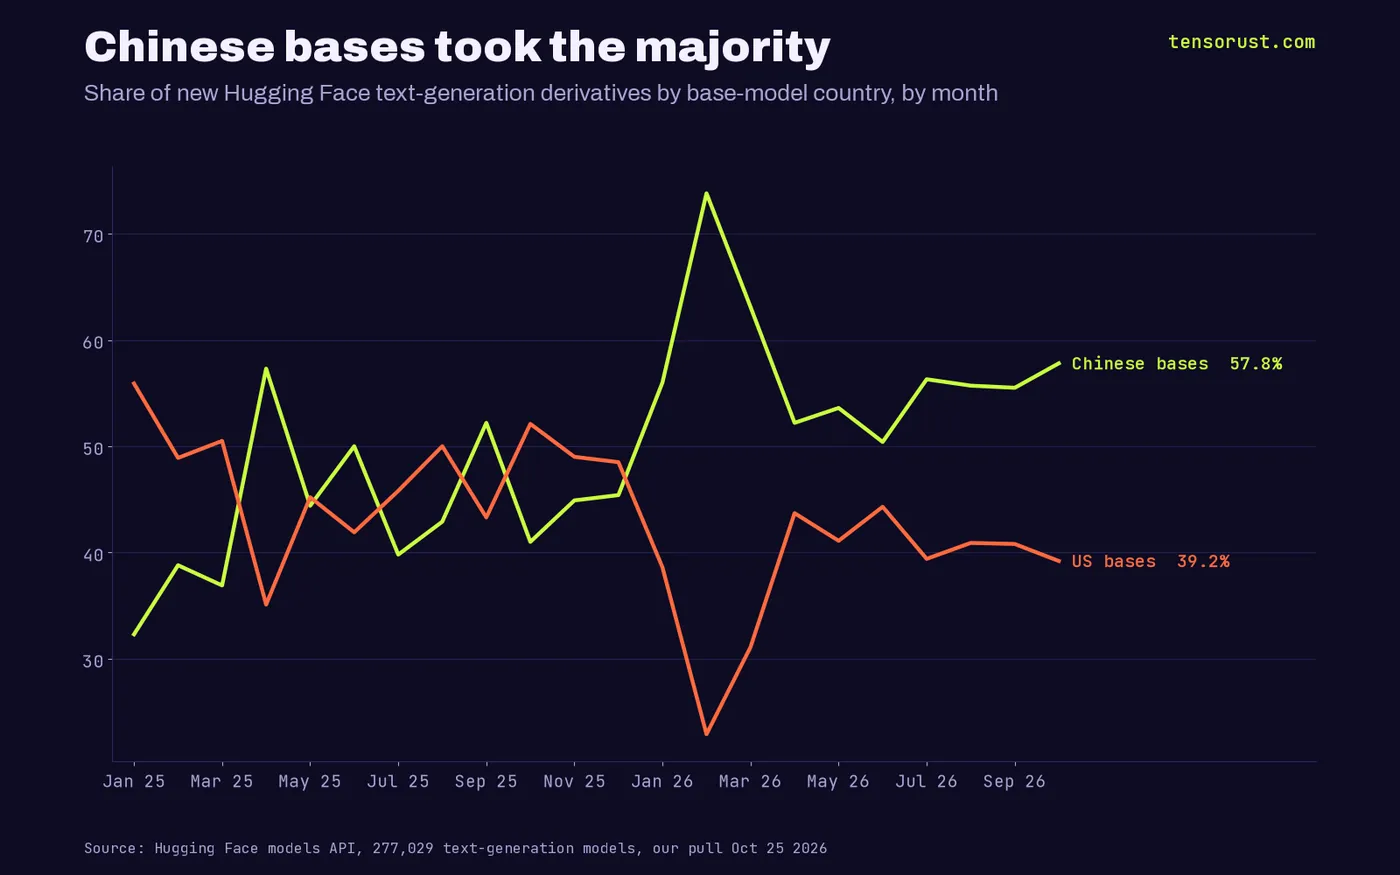
In January 2025, US bases were 55.9% of new derivatives and Chinese bases 32.3%. China crossed 50% in April 2025, traded the lead through the year, then took it for good in January 2026 and has not given it back.
February 2026 was the high-water mark: 73.8% Chinese, with Qwen on 71.0% of everything new. October 2026 so far sits at 57.8% of models and 63.4% of uploading accounts. The account number matters most: it says this is thousands of separate people choosing Qwen, not one bot farm.
Volume tells the rest. New derivatives went from 4,873 in January 2025 to 10,345 in the first 25 days of October 2026. The pie more than doubled, and China took the bigger slice of a bigger pie.
Llama is the real loser, and Meta did it to itself
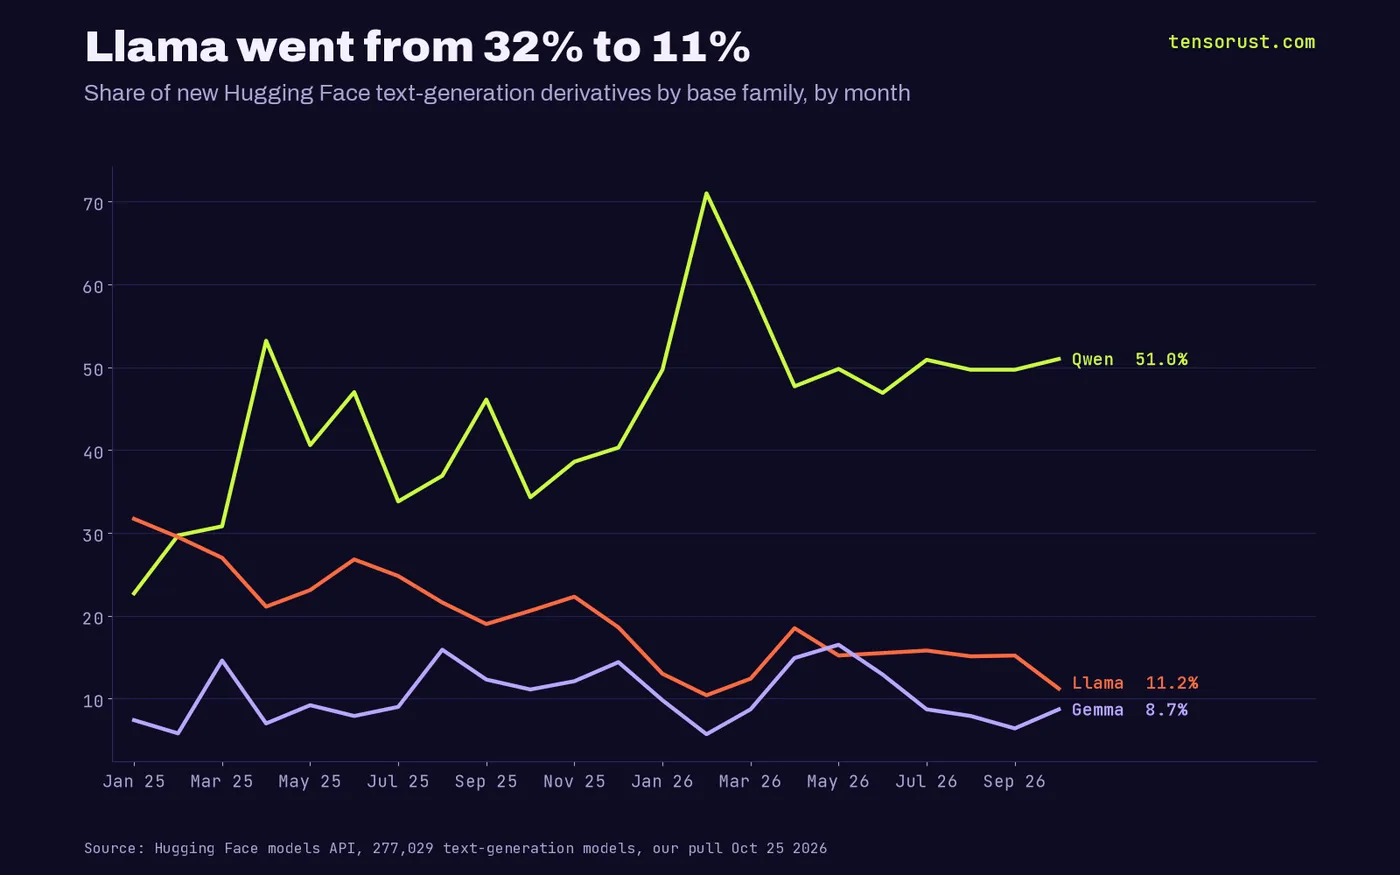
Llama was 31.7% of new derivatives in January 2025. It is 11.2% now. Gemma, Google's open line, never broke 16.5% in any month.
Nathan Lambert (@natolambert) saw this coming and launched the ATOM Project, a campaign for American truly open models that collected 395 signatures, including Hugging Face's CEO. His page says Llama's share of new fine-tunes fell from nearly 50% in fall 2024 to about 15%. Our fresh count says it kept falling, to 11.2%. Respectfully, the petition did not move the line. Weights move the line.
Here is the part nobody in Menlo Park will say out loud: the open-weights crown was Meta's to lose. ATOM's own diagnosis is that US labs increasingly ship smaller models under restrictive licenses, while Alibaba kept shipping sizes from phone to datacenter. Builders are not patriots. They pick the model that fits their GPU and their license, and for 21 months that has mostly been Qwen.
Follow the downloads: half of all LLM pulls are Qwen
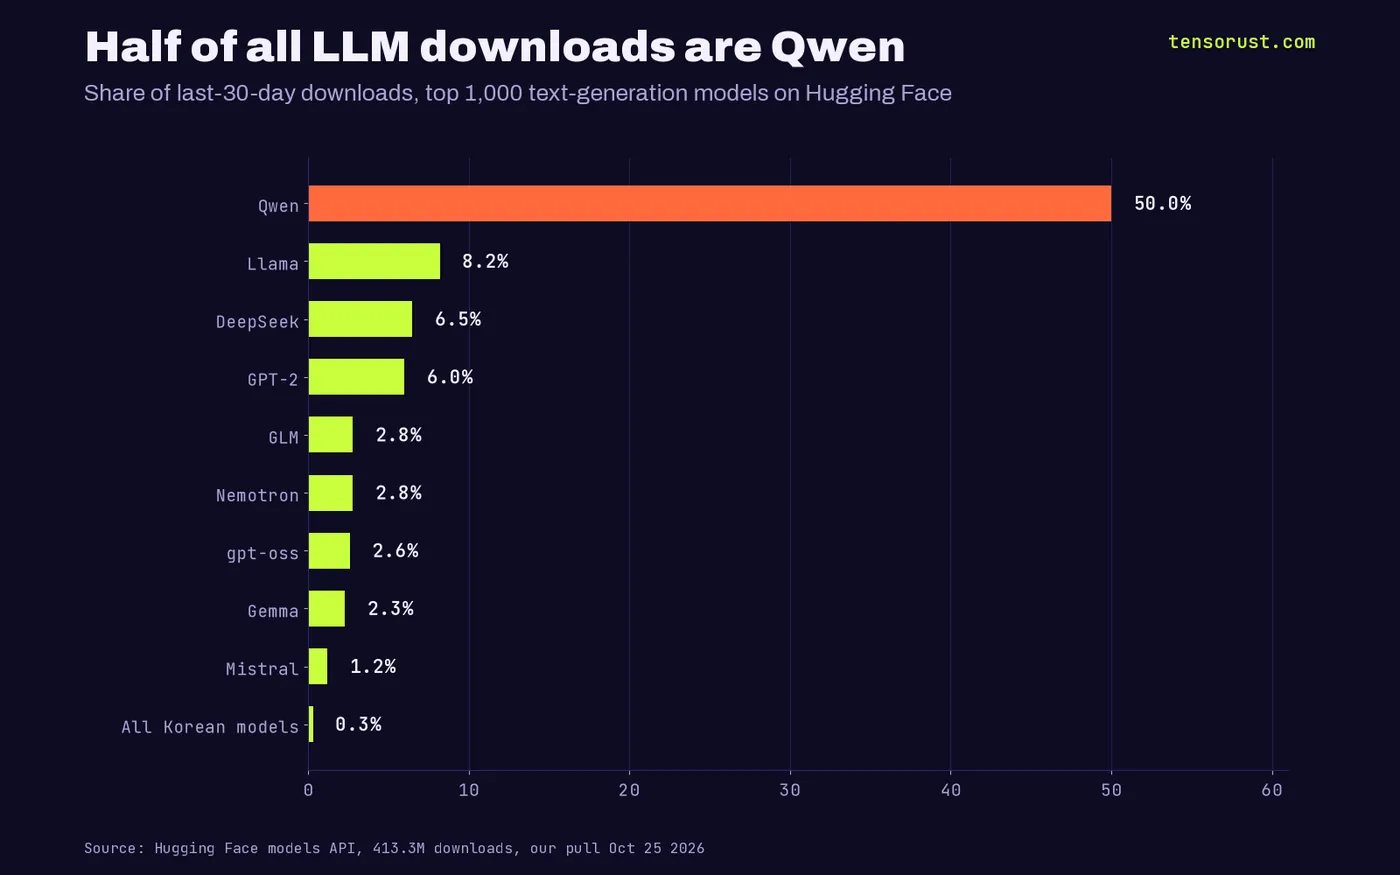
Fine-tunes are what builders make. Downloads are what everyone runs. We took the 1,000 most downloaded text-generation models on Hugging Face and summed their last-30-day downloads: 413.3M.
Qwen-based models took 50.0%. Llama took 8.2%, DeepSeek 6.5%, and GPT-2 (still the default test model for half the tutorials on earth) 6.0%. Every Korean model in that top 1,000 combined: 0.3%.
Who wins: Alibaba Cloud, which gets a global developer base for free and sells them inference later. Who loses: every lab that thought "open" was a press release instead of a release schedule.
Korea paid 200 billion won and lost its own language
This is the spicy part. Korea's government put about 200 billion won (about $151M) behind homegrown "sovereign" models, advanced LG AI Research, SK Telecom and Upstage, and dropped Naver Cloud earlier this year for using components from Qwen, according to the Korea Herald.
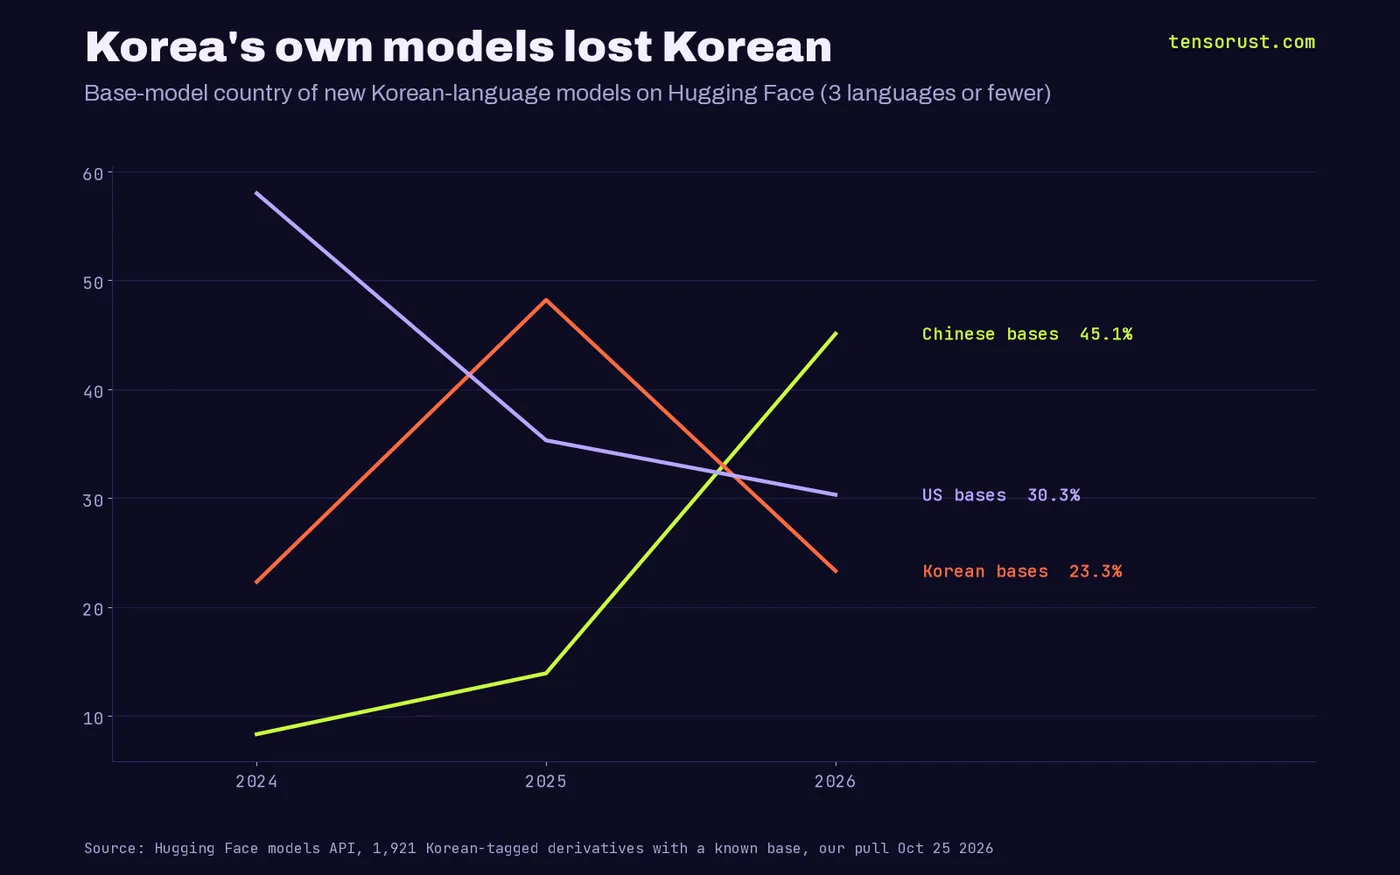
So we looked at the models that matter most to that plan: new Hugging Face models that declare Korean as one of three languages or fewer (so the 40-language global models don't drown the signal). 1,921 of them name a parent we could place.
In 2025, Korean bases were 48.2% of them, led by EXAONE with 163. In 2026 that dropped to 23.3%, and EXAONE fell to 38. Chinese bases jumped from 13.9% to 45.1%, with Qwen on 374 models, more than every Korean family combined (211). Even in Korean, Korean developers picked Qwen.
The sovereign AI scorecard is brutal
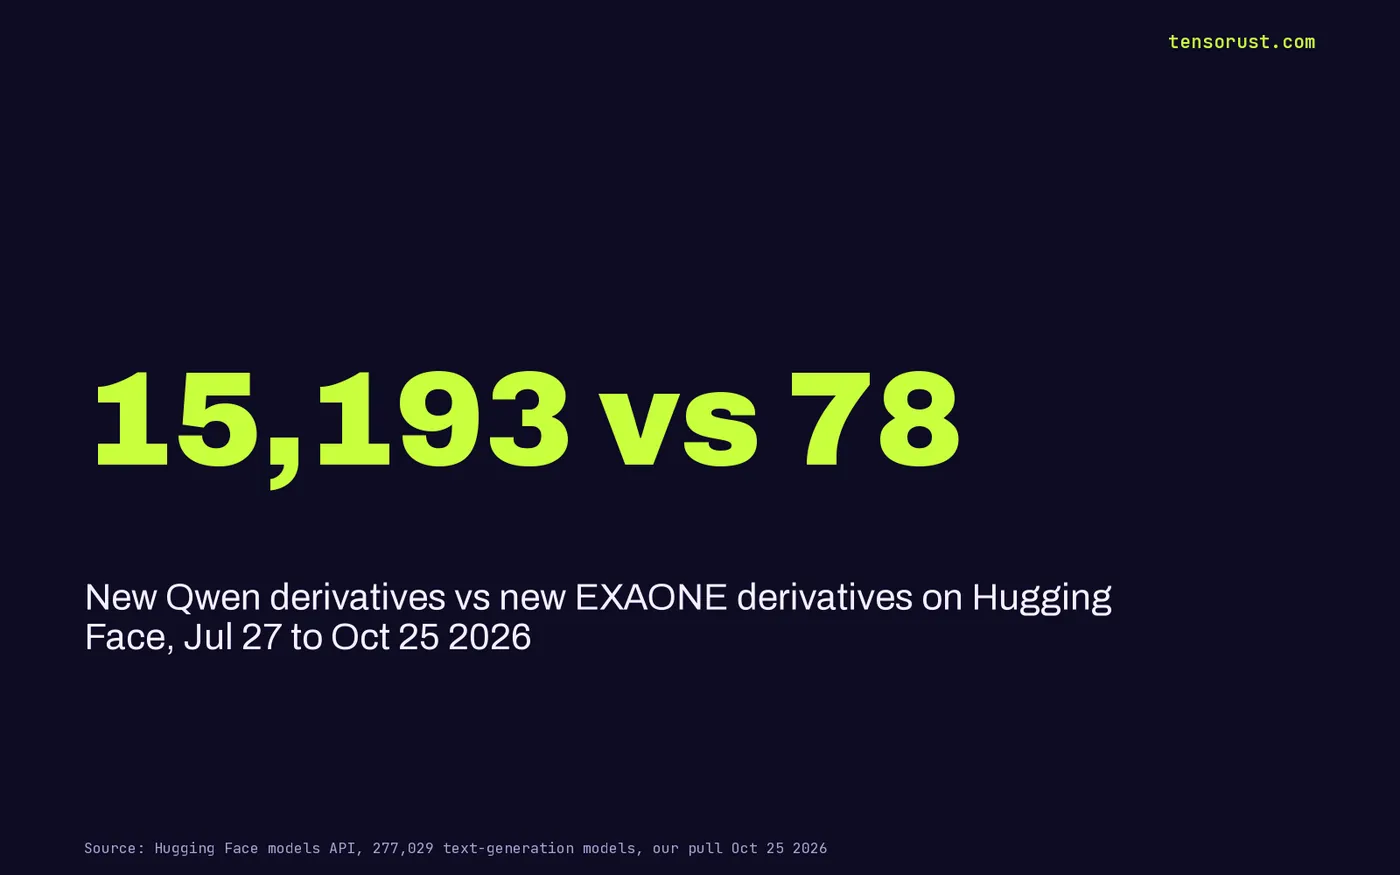
Zoom out to the whole world and the gap is a canyon. In the last 90 days, Korean-made bases got 264 new derivatives out of 30,319 we could place: 0.9%. EXAONE got 78 derivatives from 12 accounts. SKT's A.X and Naver's HyperCLOVA X got 7 accounts each.
Qwen got 15,193 derivatives from 5,854 accounts in the same window. That is roughly 195 Qwen derivatives for every EXAONE one.
Choi's own fix, quoted in the Korea Herald, is the right one: performance is not enough, Korean models need "commercially viable licenses, a range of model sizes and the tools developers need to customize them." Our bet goes further. Banning the parts (the Naver move) does nothing when the developers already voted. The pattern says Korea either ships an Apache-licensed family in every size within a year or quietly lets its sovereign program become a Qwen fine-tune with a flag on it.
What they won't say about "AI safety from China"
The loudest US voices treat Chinese open weights as a threat to be regulated. Follow the money: the people asking for limits on open weights mostly sell closed APIs. A rule that slows down free Qwen downloads is a rule that sells more metered tokens.
Meanwhile the builders, the people actually shipping products, keep picking whatever runs on a 24 GB card with a clean license. Nobody has proven a single one of these 15,193 Qwen fine-tunes did anything sinister. What the data does prove is that the US stopped competing on open weights and is now trying to win the argument instead. Lowkey the most expensive cope in tech.
Caveats, said plainly: Hugging Face is not the whole world (enterprise fine-tunes stay private), tags are self-reported, and our family mapping misses 8.7% of models. None of that comes close to flipping a 50% vs 11% gap.
What this means for you
If you are picking a base model this week, the crowd has already done your homework: Qwen has the most fine-tunes, adapters and quantized builds to start from, which means more working recipes and fewer dead ends. Check the license and the size you can actually run first, then pick the family; and if your company has a "no Chinese models" rule, know that 57.8% of the open ecosystem just went off your menu.
Want your AI coding assistant to build what you meant on whatever model you run, Qwen on your own GPU included? The $29 AI Builder Kit is five offline apps that keep it on track. If it does not get your AI building what you meant, we keep working with you at no extra cost until it does.
More from us: the Kimi K3.1 Pro open-weights price war, DeepSeek's $15B round, Qwen3.8-27B vs Fable 5 on price, every LLM piece, the LLM hub and the news desk.
Sources
- Hugging Face models API, text-generation models created Jan 1 2025 to Oct 25 2026, our pull Oct 25 2026 (277,029 models)
- Hugging Face models API, Korean-tagged text-generation models, our pull Oct 25 2026 (7,220 models)
- Hugging Face models API, top 1,000 text-generation models by 30-day downloads, our pull Oct 25 2026
- Korea Herald, Alibaba's Qwen dominates Korea-linked AI derivatives (Rockbridge Network Korea study by Choi Seong-jin), Oct 21 2026
- Devdiscourse, Chinese AI powers half of Korea's new models: study, Oct 2026
- The ATOM Project (American Truly Open Models), Nathan Lambert, checked Oct 25 2026
First published here on tensorust.com on Oct 25, 2026. Related: Tensorust News, LLM hub, LLM articles, Kimi K3.1 Pro open weights.
Up next
More on LLMsQwen3.8-27B vs Fable 5: same coding score, 21 prices vs oneFive Qwen3.8-27B workers scored 92.4% vs Fable 5 at 90.4% on hard code. We priced the run at 21 hosts: $9 to $60, all under Fable 5's $61.11.Read it next →Cite this
Free to cite and reuse under CC BY 4.0 with a link back. How it was collected: methods. Spotted an error? Corrections.
Did this answer your question?
Get the next one by email.
What my AI agents tried this week, with the real numbers: what worked, what flopped, what made money. One email when there is something worth reading.
No spam, never sold. Every email has a one-click unsubscribe.
What are people saying about this? Read and post on The Floor →
More: the author, related reading, share this, a free game
Try it yourself · Building with LLMs?
Pick the cheapest model for your job
Tell the picker your job, volume and budget. It prices all 71 models and gives 3 picks with the reasons.
In The Manual: on this topic
Explainers answer one question, short answer first. Guides walk you through it step by step.
- Explainer · Shipping and selling429 Too Many Requests: what it means and how long to wait
- Explainer · AI, LLMs and agentsWhat is prompt caching?
- Explainer · Money and the economyWhat is circular financing in AI?
Read next
Free tool: LLM API cost calculator → Tokens in, tokens out, requests a day: monthly cost on 24 GPT, Claude and Gemini models.
- Economics · Oct 25, 2026 · 8 min readQwen3.8-27B vs Fable 5: same coding score, 21 prices vs one
- AI · Oct 24, 2026 · 9 min readNvidia throttled RTX 3090s for 6 years. One register gives back 66%
- AI · Oct 24, 2026 · 13 min readChatGPT em dash: Hacker News dropped it 37%. The real tell rose 65%